
AI AND BI PIPELINES
AI-ready data is the curated set, not the whole estate.
AI-ready data starts with knowing which files are current, approved, and allowed. Diskover indexes the estate, enriches each record with owner, project, version, and sensitivity, and delivers curated datasets to your AI and BI pipelines, so models train on the best files rather than the most.
WHY CURATION
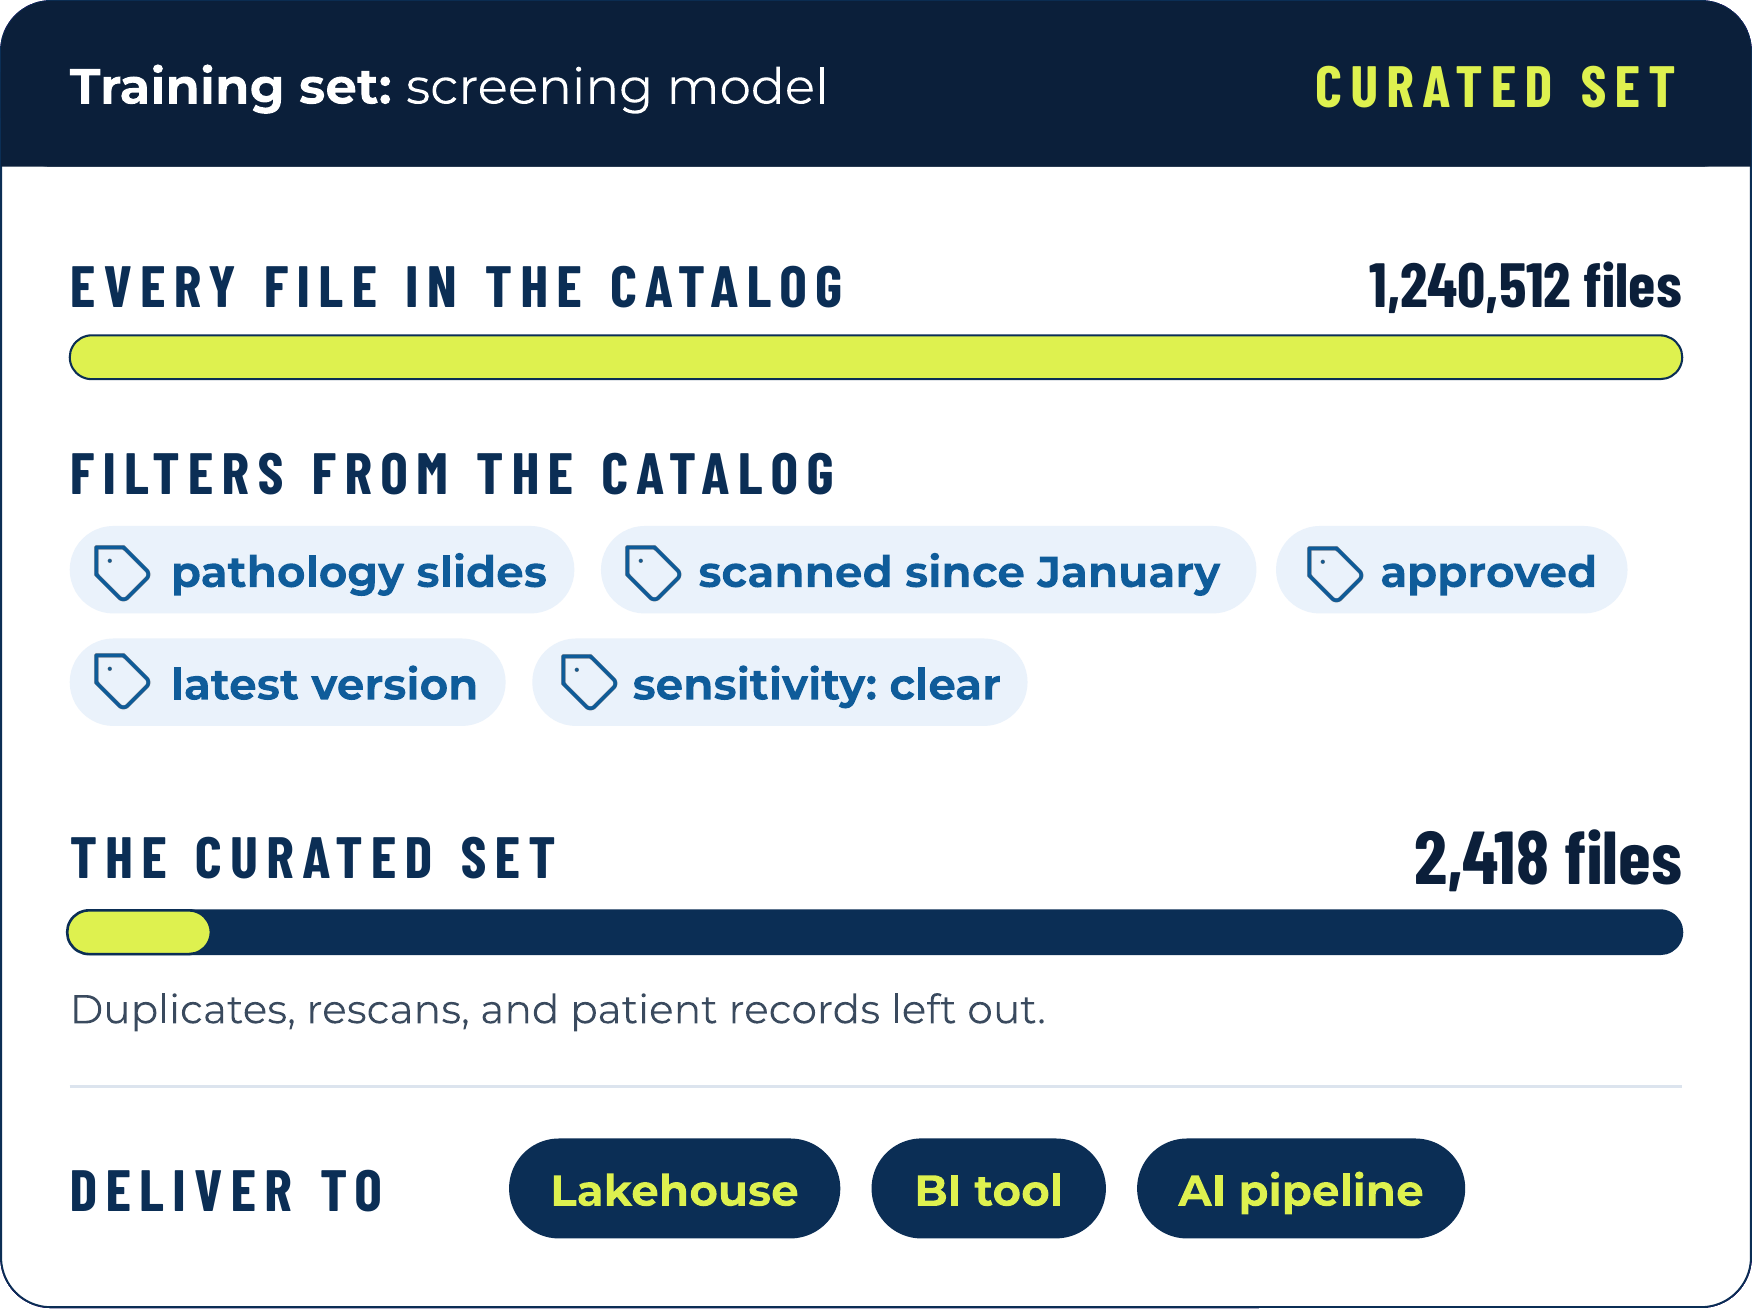
Every file in a training set costs compute.
A duplicate, a stale version, or a restricted file costs the same compute time as a good one. Diskover selects the set from the metadata catalog first, so your pipelines receive files that are current, approved, and allowed.
HOW IT WORKS
How Diskover prepares AI-ready data.
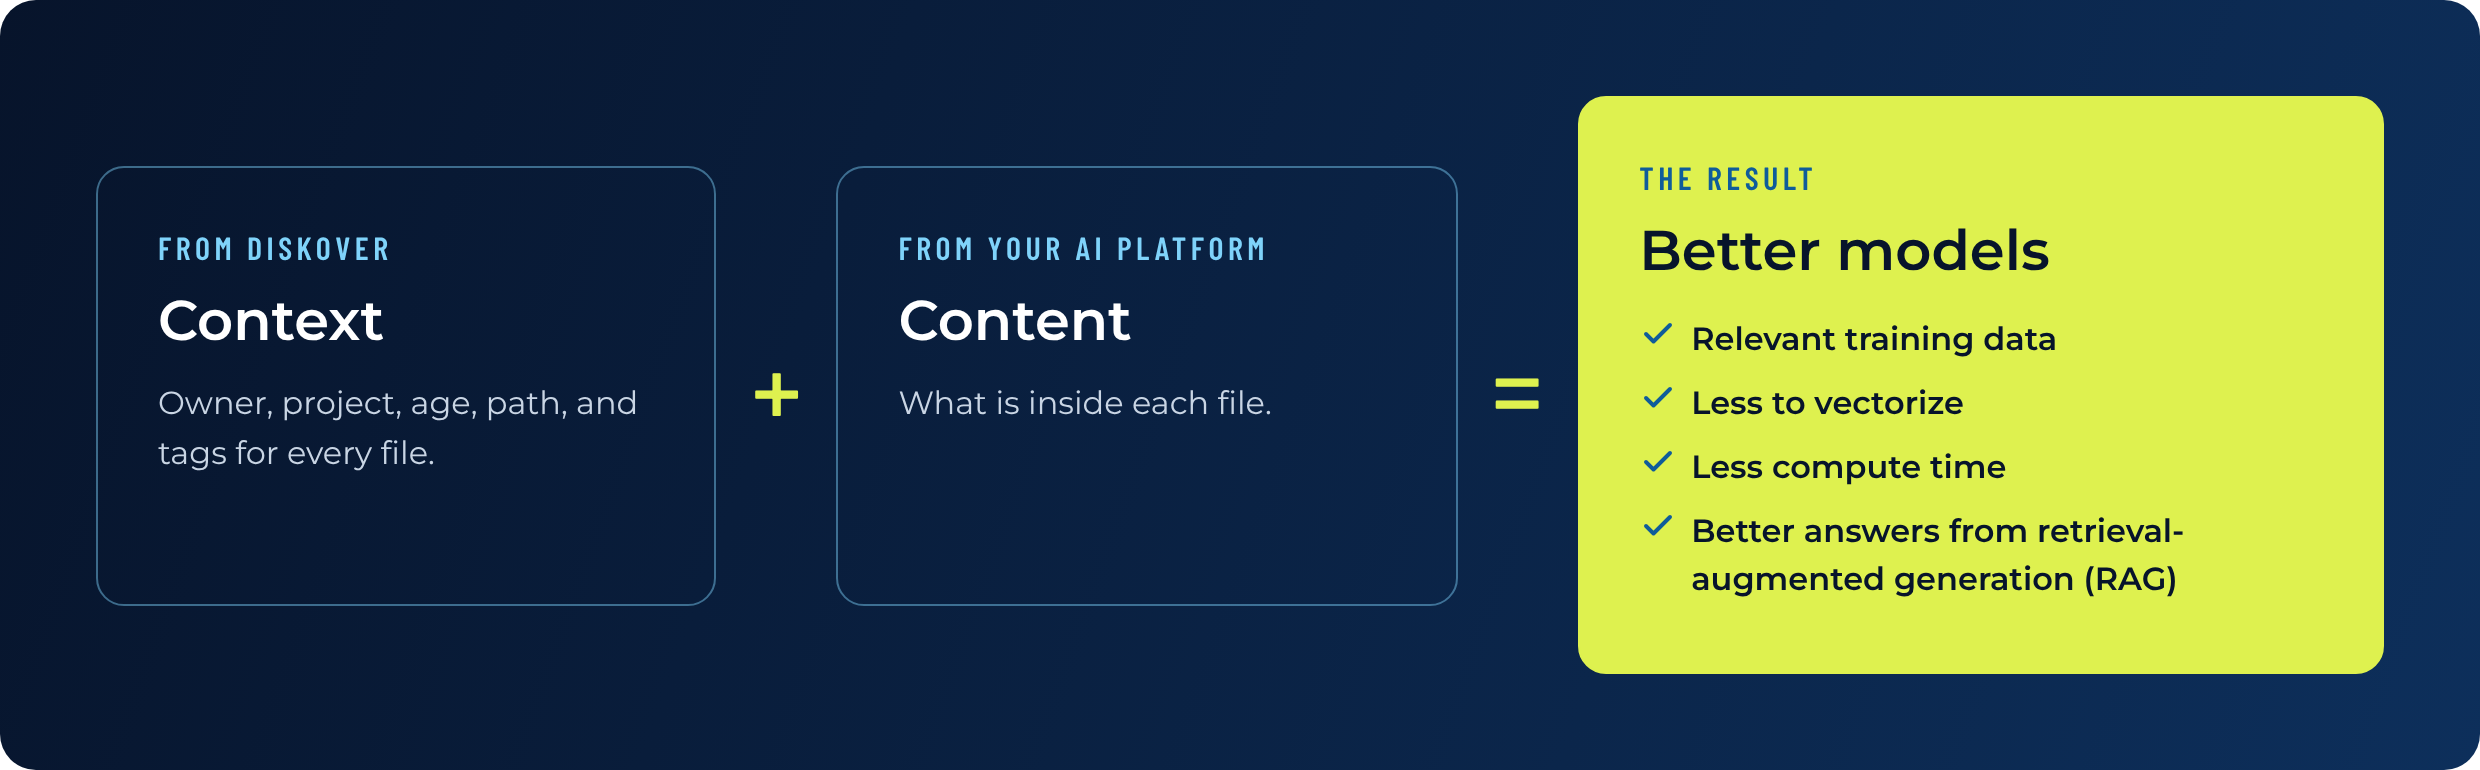
Diskover indexes every file in place, enriches each record with business context, and curates the set with filters and tags. The data moves only when a workflow delivers it to your lakehouse, BI tool, or AI pipeline.
BENEFITS
Why it matters.
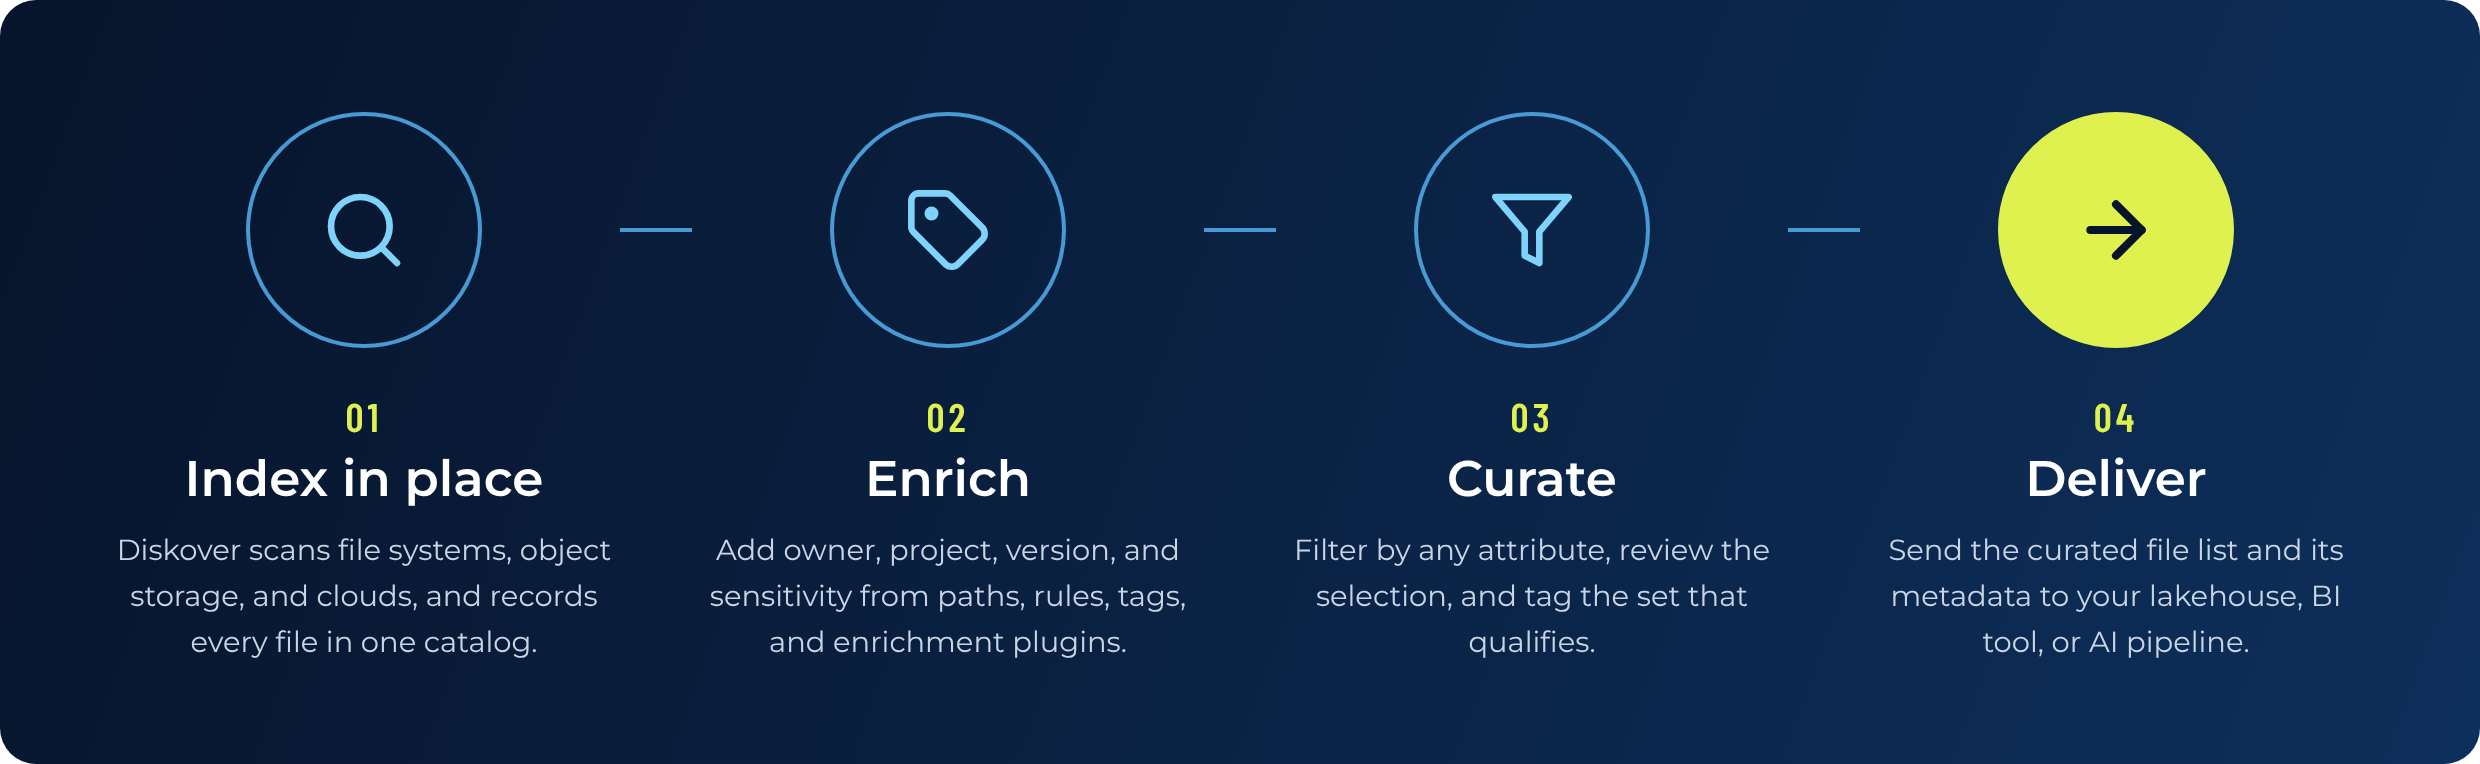
Context models can use.
Fewer errors from bad inputs.
Reports on the same catalog.
Datasets you can trace.
PROOF
Why AI-ready data pays off.
$250K
in storage overspend avoided at a cancer research institute, while its AI data pipelines kept running
Source: Diskover customer
60%
of AI projects unsupported by AI-ready data will be abandoned through 2026, Gartner predicts
Source: Gartner, 2025
USE CASES
How data preparation turns noise into signal.
AI AGENTS
From AI-ready to agent-ready.
AI agents choose their own data while they work, so the whole estate has to be described, current, and tagged. Read why agent-ready data is a different standard, and see how the AI Connector lets AI tools and agents search the same catalog.
AI-READY DATA
A person picks the set.
A team chooses the files before the model runs. They filter the catalog by owner, project, version, and tag, review the selection, and tag the approved set. The model trains only on that set, and you can trace every file in it later.
AGENT-READY DATA
The agent picks the files.
The agent chooses files while it works, one question at a time. It searches the catalog with the same group permissions as your team, so it sees only what it is allowed to see. Tags tell it which files are current and approved, and a person approves each tag it adds.
FAQ
Questions about AI-ready data.
See it on your own data.
We’ll index a sample of your environment and show you what’s recoverable against your current storage spend.