
DATA LAKES AND LAKEHOUSES
Send the lakehouse only the files that belong there.
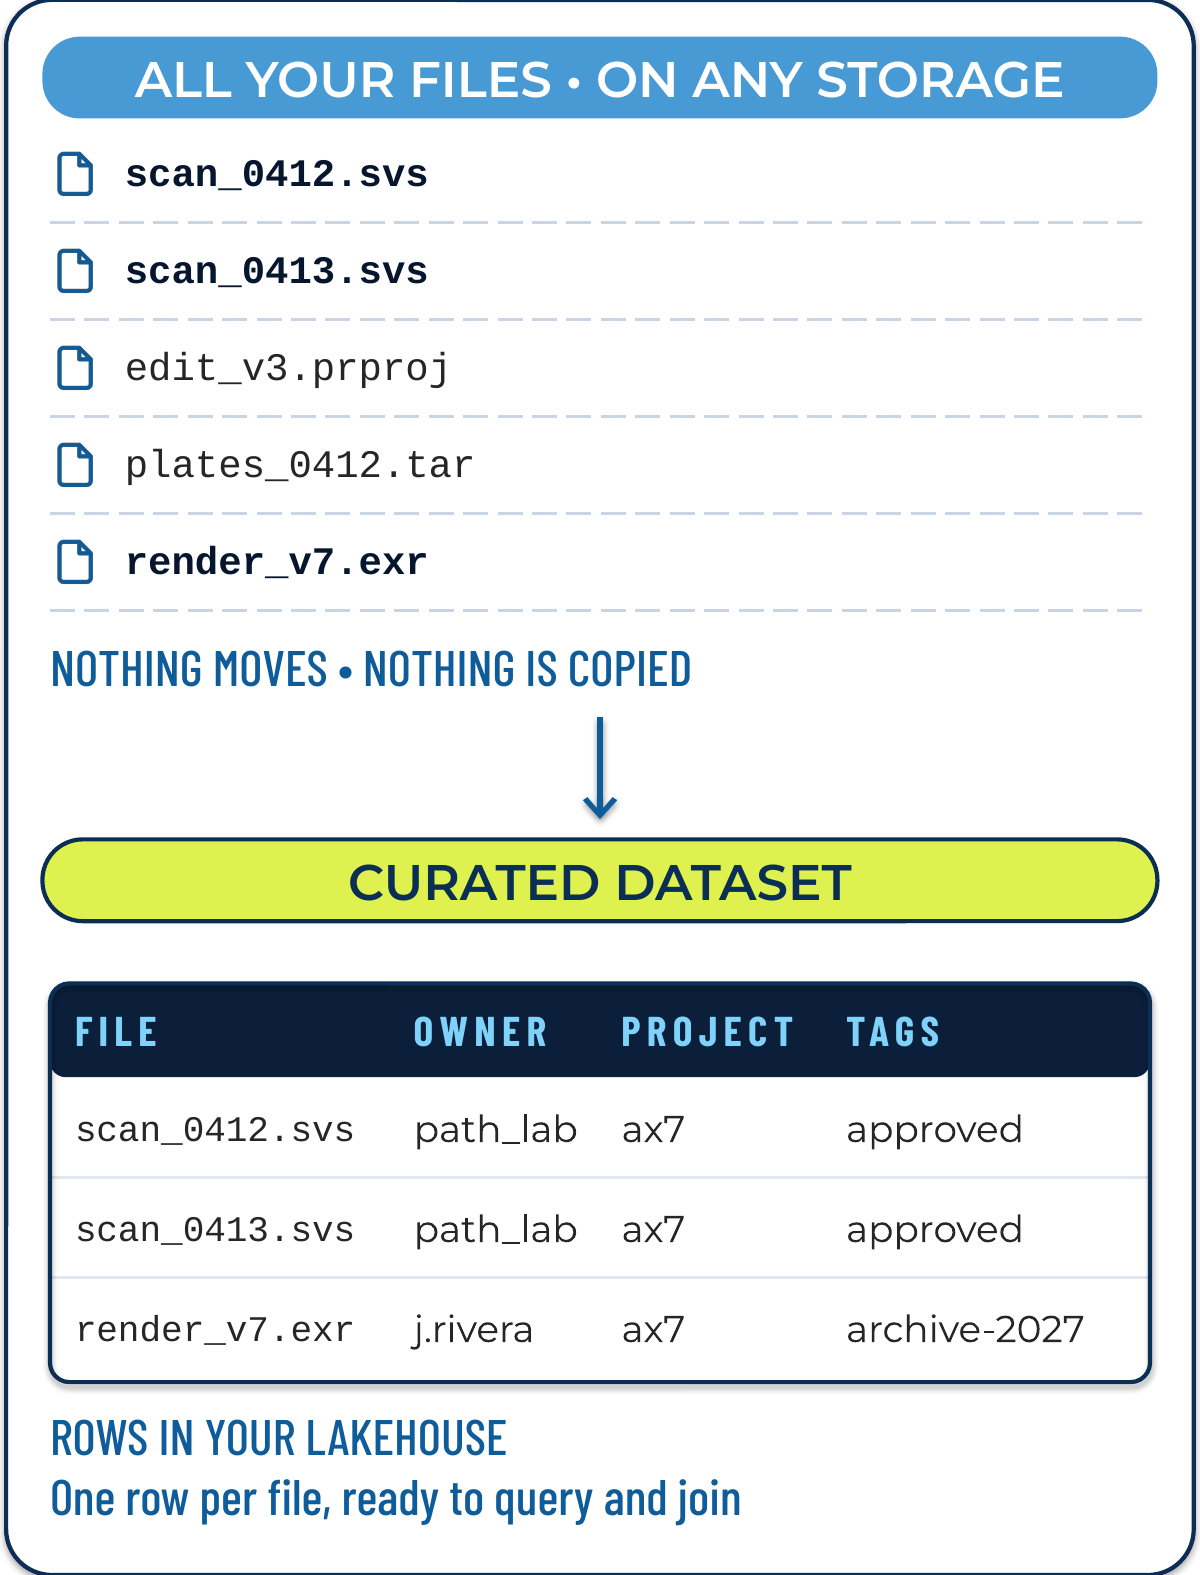
Your lakehouse queries rows, while most of your data lives in files. Diskover indexes the lake and every other storage system in place, adds business context, and delivers a curated set of file metadata as queryable rows to the Dell Data Lakehouse, Snowflake, or the platform you run. The files stay on the storage you already own.
WORKS WITH YOUR LAKEHOUSE • DELL DATA LAKEHOUSE • SNOWFLAKE
THE PROBLEM
Most of your data never reaches the lakehouse.
Gartner puts unstructured data at 70% to 90% of enterprise data. It sits in files on network storage, object storage, and clouds, outside the tables your analysts and AI tools query. Copying all of it into the lake brings duplicates, stale versions, and restricted files along with the useful ones.
Diskover describes every file first, then sends the lakehouse a curated set of rows that it can query, join, and trust.
BENEFITS
Why it matters.
Your lakehouse already holds your business data. Diskover adds your files: a clean table of the ones that matter, ready to join with sales, project, or research data for analytics and AI.
Files become queryable.
Lower storage and compute costs.
Traceable AI datasets.
WHAT GETS DELIVERED
What the lakehouse receives.
Each file becomes one row, with the context your queries need. The file content stays on your storage until a workflow or a query calls for it. Analysts join file metadata with the tables they already have, such as projects, cost centers, or sales, in the tools they already use.
Core fields.
Business context.
Decisions.
DELIVERY
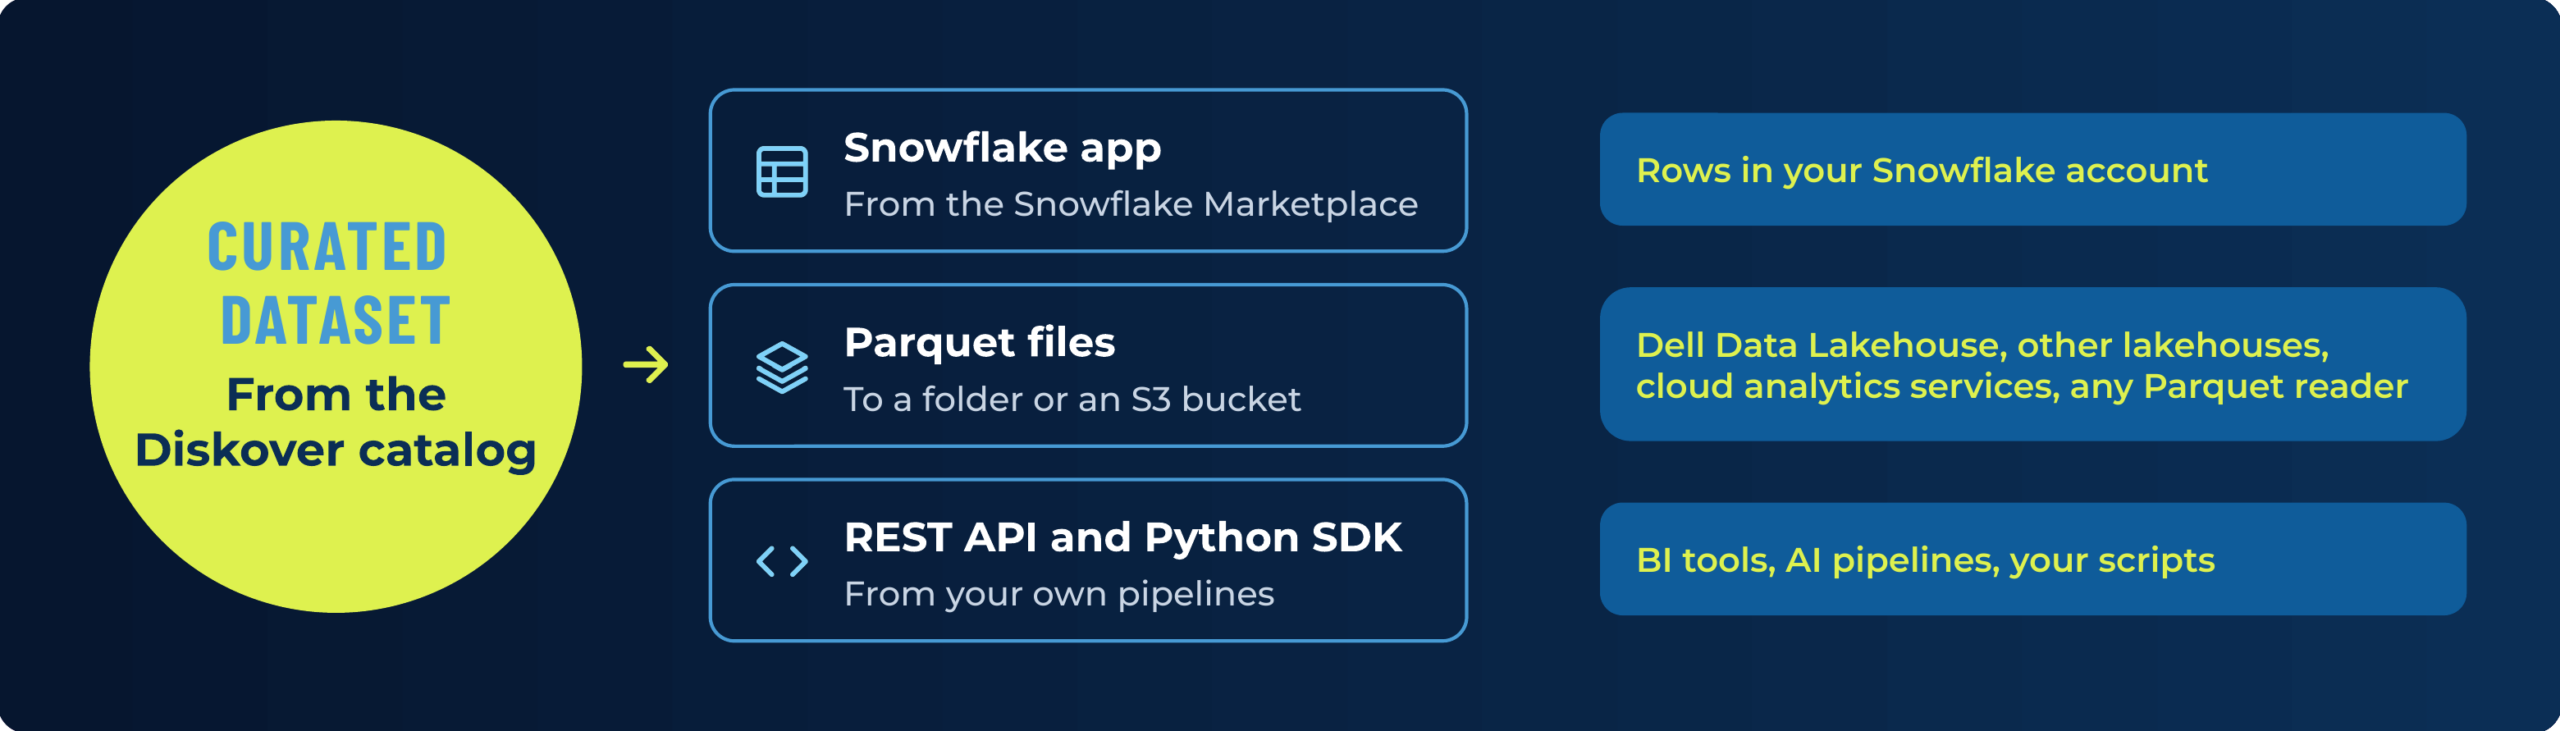
Three ways to deliver.
THE DATA LAKE
Keep the lake itself in shape.
A data lake is storage too, and it fills with the same duplicates, abandoned runs, and stale extracts as any file share. Diskover indexes the lake in place with your other storage, so the same reports, tags, and policies clean it up.
BETTER TOGETHER
Partners.

Dell Data Lakehouse
Diskover indexes PowerScale and the lakehouse in place, and organizes file metadata before it reaches the lakehouse, so analytics and AI pipelines work from curated datasets.
Snowflake
Diskover delivers curated file metadata as queryable rows, ready for analytics, dashboards, and Snowflake Cortex.
FAQ
Questions about unstructured data in the lakehouse.
See it on your own data.
We’ll index a sample of your environment and show you
what’s recoverable against your current storage spend.