

UNSTRUCTURED DATA MANAGEMENT PLATFORM
The metadata control plane for your unstructured data estate.
Diskover indexes every file across every storage vendor, tier, and location, without moving or copying a thing, so you can cut storage costs, tighten governance, and deliver AI-ready data.
THE CHALLENGE
Data grows faster than anyone can track it.
Unstructured data grows every day, across every storage system you run. Without a single view, costs rise, files get lost, and good decisions take longer.
Costs keep climbing.
Teams buy more storage because they can’t see what is cold, duplicated, or forgotten.
AI projects start with the wrong data.
Teams spend weeks cleaning and searching before a model sees a single file.
Files are hard to find.
Data is spread across vendors, sites, and clouds, and each system has its own tools.
Risk stays out of view.
Old and orphaned files sit unowned, and nobody can say what should be kept.
WHAT IS DISKOVER
A single source of truth for every file you own.
Bring all your data, from edge to cloud, into one easy-to-manage metadata catalog so you can search, organize, and automate data wherever it lives. Your data stays in place while the catalog is built, and it moves only when a workflow calls for it.
1.4B
files indexed in 2 hours,
that’s ~200K files per second
435+
features including plugins, connectors, and API endpoints
30–50%
average storage reclaimed running a single catalog-led approach
WORKS WITH WHAT YOU ALREADY RUN
Your storage, your clouds, one catalog.
Vendor-neutral by design. Diskover connects to your storage, clouds, and analytics tools, and brings them all into one catalog.



WORKS ACROSS Cloud • On-premises • Hybrid • NAS • SAN • Object • Tape • Archive • Data lakes • Lakehouses • AI/BI/ML
WHERE IT PAYS OFF
Four ways Diskover pays for itself.
Most estates hold the same project on fast storage, on an archive tier, and in a cloud bucket at once. A metadata catalog counts it once, shows what it costs, and makes defensible deletion a rule rather than a project.
$10M
saved by one global media company after reclaiming 8 PB of its data estate
$542K
storage cost reclaimed within days of the first index
30+ hours
a week returned to data teams from manual data housekeeping
Lower storage spend.
Reclaim 30% to 50% of capacity by finding cold and duplicate data before you buy more.
AI results you can trust.
Leave stale and duplicate files out of training sets, so every compute dollar goes into accurate results.
Work that runs itself.
Set a rule once. Diskover moves, tags, or archives data on schedule, and your team gets time back.
The right data on the right tier at the right time.
Move files between fast, archive, and cloud storage automatically, based on age, owner, or project.
AI CONNECTOR
Talk to your data.
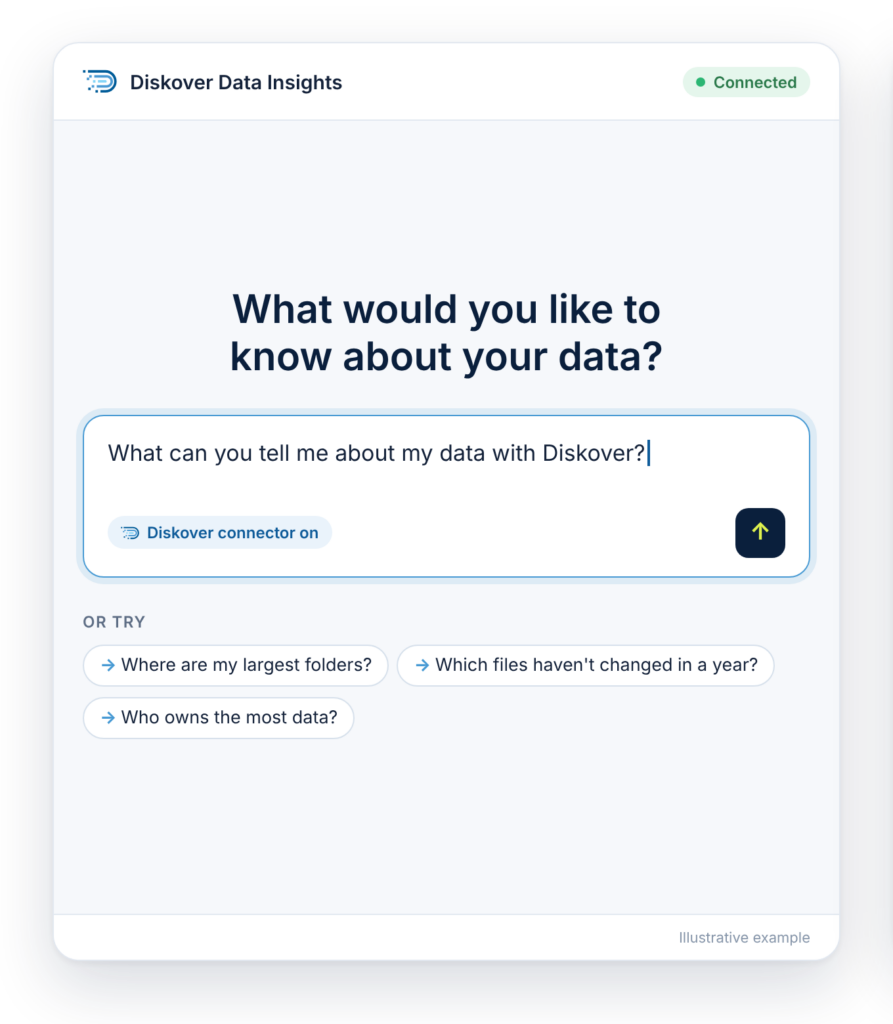
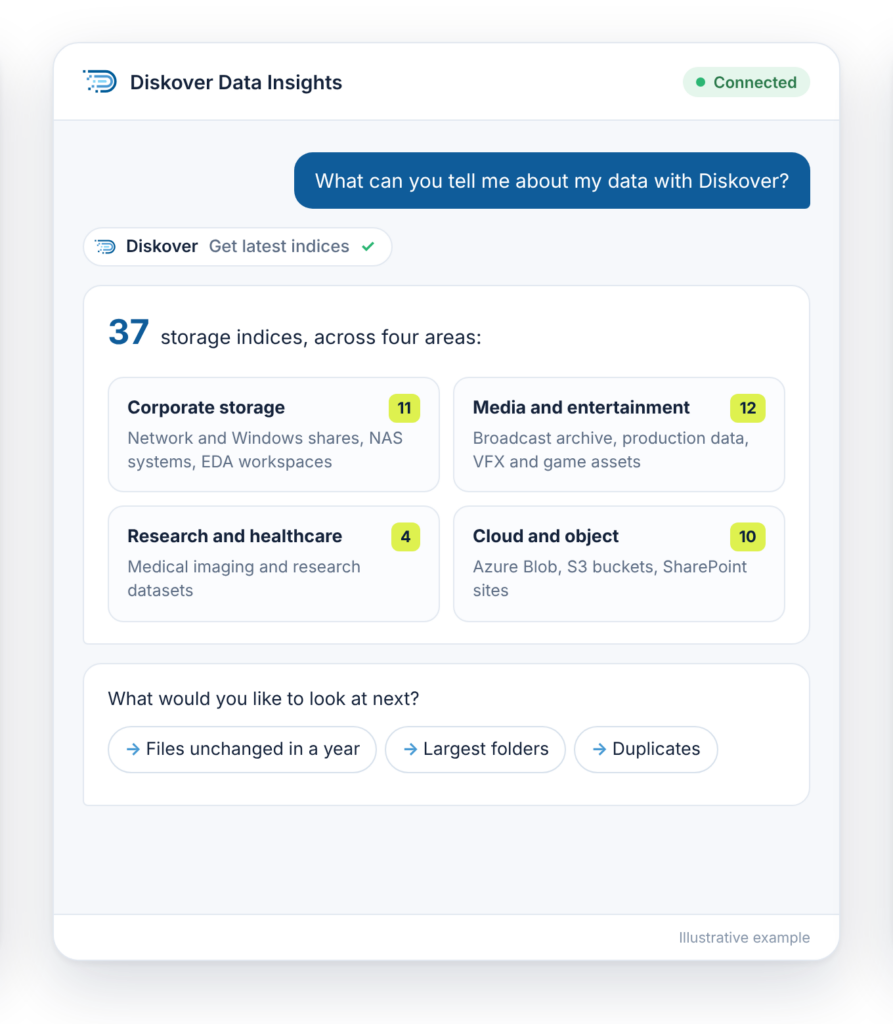
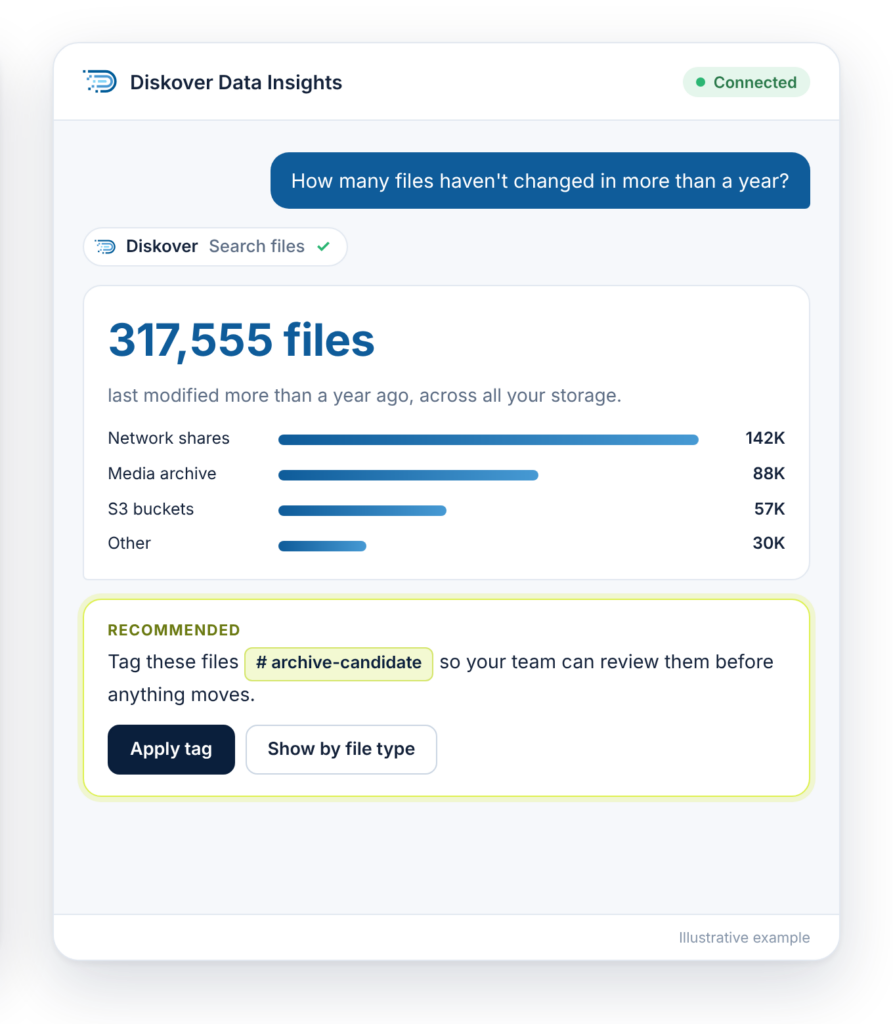
Ask a question about your storage in plain language. Diskover answers from its catalog of every file, then suggests the next step. AI-assisted, human-approved. Nothing runs until you say so.
01
ASK
Type a question the way you would ask a colleague.
02
REVIEW
See the matching details with a recommended action.
03
APPROVE
Accept the recommended action, and Diskover runs it.
PROOF IN PRODUCTION
Built for estates measured in billions of files.
From media archives to chip design, Diskover helps teams cut storage costs, govern their data, and deliver clean datasets for AI and BI.
100B+
files cataloged
across 4 data centers
4,000+
engineers and operational users at one customer
260 PB
of unstructured media content indexed across several locations
Media, Entertainment, and Gaming.
Move finished projects off premium storage and keep every master easy to find.
Semiconductor and EDA.
Clear old simulation runs, debug logs, and core dumps, and give fast storage back to active designs.
Energy.
Find seismic and survey data by file type, project, and age, across every site and every decade.
Life Science and Healthcare.
Keep instrument and imaging data easy to find, and move older research data to lower-cost storage.