

LIFE SCIENCE DATA MANAGEMENT
Your research data, in full view.
Life science data management from sequencer to publication: Diskover indexes sequencing, imaging, and clinical research files across HPC, lab NAS, object, and cloud, in place. Researchers find data by study, research IT sees cost by lab, and data stewards see where likely patient files sit.
$542K
of data estate reclaimed within days of the first index
Diskover life science customer
$250K
in storage overspend avoided at a cancer research institute
Diskover life science customer
27M
pathology files indexed across 3 sites
Diskover life science customer
THE PROBLEM
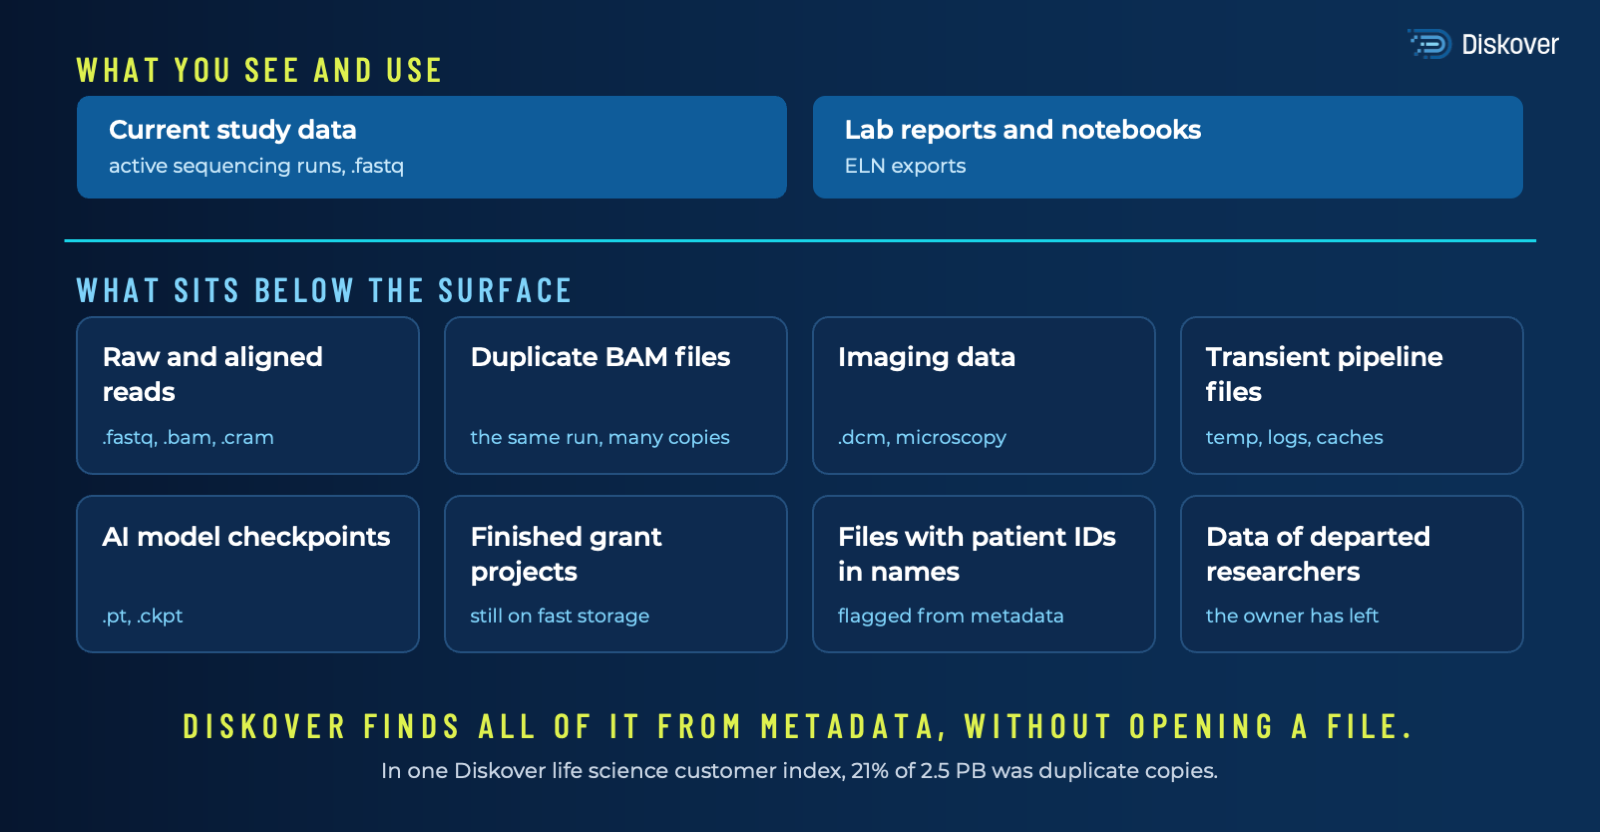
Researchers see the tip. Storage holds the rest.
Sequencers and imaging systems add data every day, and pipeline output outlives the analysis. In one Diskover life science customer index, 21% of 2.5 PB was duplicate copies.
HOW IT WORKS
From scattered files to clear action.
BUILT FOR LIFE SCIENCE
Diskover speaks life science.
Adds sequencing details.
Tracks storage by lab.
Knows your file types.
Gives visibility without access.
WHO FEELS IT
Three teams. Three different pains.
WHY IT MATTERS
Fund research, not storage.
Gartner expects demand for data center storage capacity to grow 19.5% a year through 2029. Research budgets do not grow that fast. With context on every file, labs put a cost on storage, keep fast storage for active studies, and answer funders with confidence.
AI READINESS
Prepare research data for AI before it reaches a model.
REAL-WORLD USE CASE
$542K reclaimed, within days of the first index.
A cancer research institute, with 4.7 PB of research and clinical storage across 3 sites.
27M
pathology files
4.7 PB
research storage
3
sites
1 PB
over 5 years old
THE CHALLENGE
- Research and clinical data growing across 3 sites.
- Temporary and test data filled core storage.
- AI pipelines needed data, without storage overspend.
HOW THEY USE DISKOVER
- Indexed pathology files across all 3 sites in one metadata catalog.
- Found 0.5 PB of temporary, transient, and test data.
- Flagged 1 PB of files over 5 years old for tiering.
$542K
of data estate reclaimed within days of the first index
$250K
in storage overspend avoided, with AI data pipelines kept running
0.5 PB
reclaimed from core research and clinical storage
FAQ
Common questions.
See it on your own research data.
We will index a sample of your storage and show you what is recoverable against your current storage spend.