
SEMICONDUCTOR AND EDA DATA MANAGEMENT
Every design file, in full view.
EDA data management for semiconductor teams: Diskover indexes design, simulation, and verification data across every filer, object store, and archive, in place. Engineers find the run they need, CAD and IT see what is safe to move, and tapeout data is tagged for protection.
103B+ files
in one searchable index at a semiconductor company
Diskover semiconductor customer
36 PB
of storage across 17 locations
Diskover semiconductor customer
MILLIONS
saved annually by controlling storage utilization across sites
Diskover semiconductor customer
THE PROBLEM
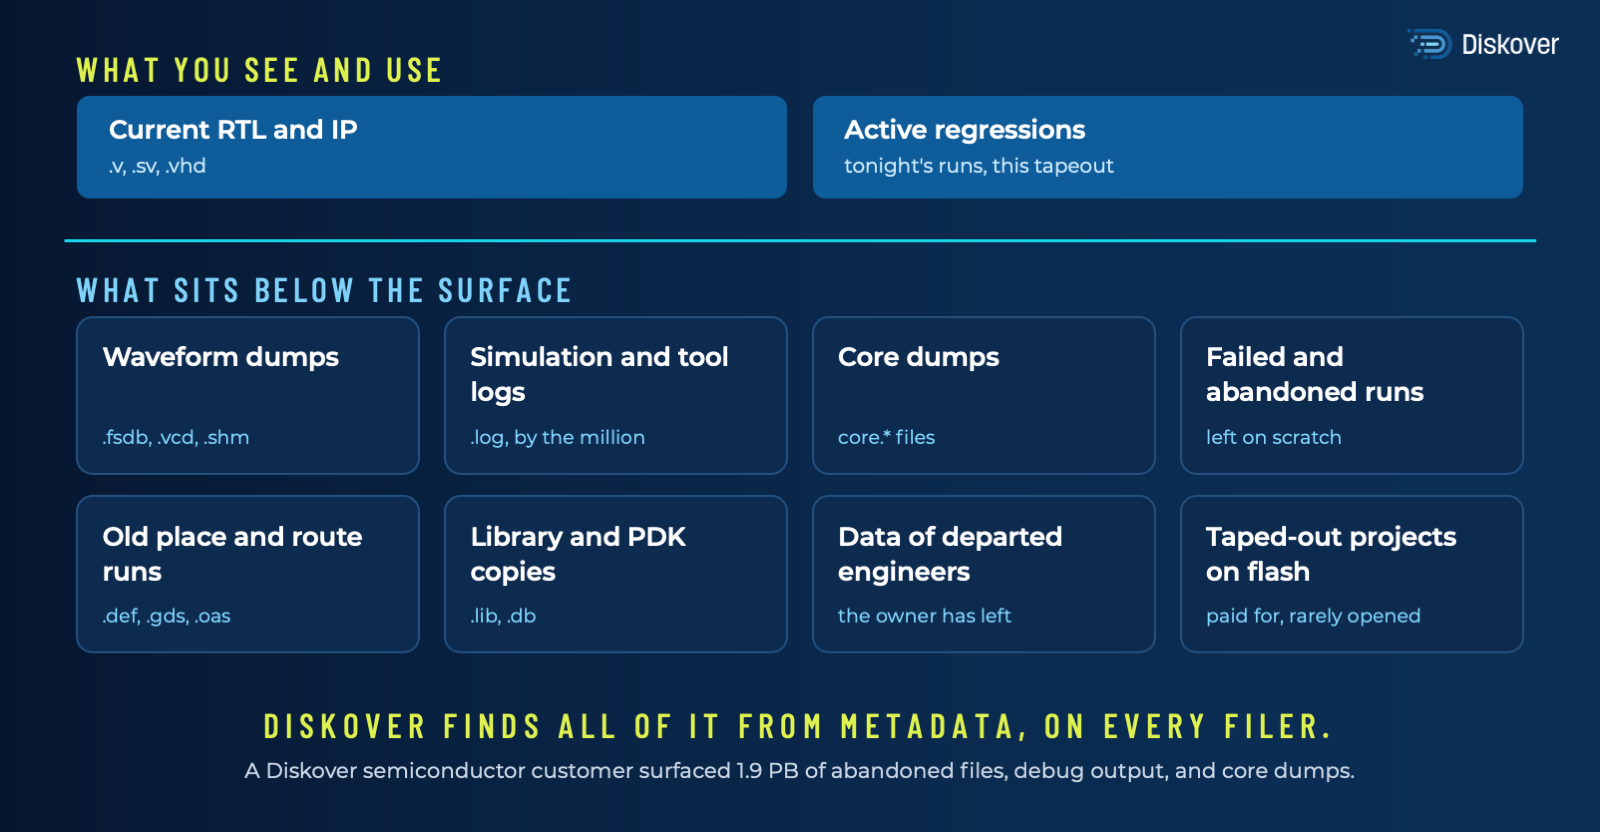
Engineers see the tip. Filers hold the rest.
Every tapeout leaves waveforms, logs, and old runs behind. They pile up on fast storage, tapeout after tapeout, while the next regression waits for room. Much of it can be regenerated, and nobody plans to open it again.
HOW IT WORKS
From scattered files to clear action.
BUILT FOR EDA
Diskover speaks EDA.
Knows your design files.
Traces failed jobs.
Adds business context.
Self-service archive.
WHO FEELS IT
Three teams. Three different pains.
WHY IT MATTERS
Spend on tapeouts, not on old runs.
Gartner expects NAND flash prices to rise 202% in 2026. When old regressions fill flash filers, every new project pays for them. With context on every file, teams put a cost on storage, keep flash for active work, and know where restricted IP lives.
AI READINESS
Prepare design data for AI before it reaches a model.
REAL-WORLD USE CASE
103 billion files. One searchable index.
A $314B semiconductor company, across 4 global locations and 600 projects a day.
103B+
files indexed
100+ PB
of design data
~8,000
storage volumes
~4,000
engineers and data users
THE CHALLENGE
- Design data spread across 4 locations and thousands of volumes.
- Cleanup depended on manual, project-by-project work.
- Storage use was hard to control across sites.
HOW THEY USE DISKOVER
- One index across every site and volume.
- Diskover opened to engineers, not only IT, so data owners clean up their own data.
- Automated cleanup policies, run on a schedule.
$250K a year
in opex saved through automated cleanup policies
Millions
saved each year by controlling storage use across sites
600
projects processed per day, from one index
FAQ
Common questions.
See it on your own design data.
We will index a sample of your filers and show you what is recoverable against your current storage spend.