

SOLUTION BRIEF | ENERGY, OIL AND GAS
From seismic to first oil, every file accounted for.
One enriched metadata catalog for exploration, simulation, and production data across HPC, NAS, object, cloud, and tape.
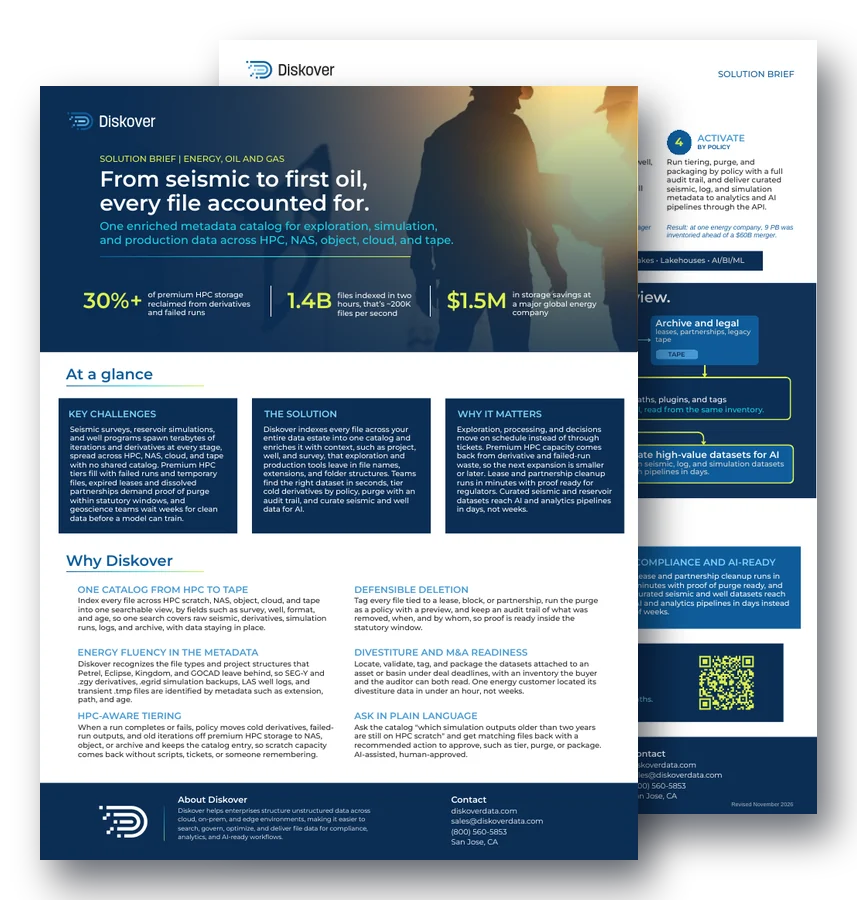
30%+
of premium HPC storage reclaimed from derivatives and failed runs
1.4B
files indexed in two hours, about 200K files per second
$1.5M
in storage savings at a major global energy company
At a glance.
Key challenges.
Seismic surveys, reservoir simulations, and well programs spawn terabytes of iterations and derivatives at every stage, spread across HPC, NAS, cloud, and tape with no shared catalog. Premium HPC tiers fill with failed runs and temporary files, expired leases and dissolved partnerships demand proof of purge within statutory windows, and geoscience teams wait weeks for clean data before a model can train.
The solution.
Diskover indexes every file across your entire data estate into one catalog and enriches it with context, such as project, well, and survey, that exploration and production tools leave in file names, extensions, and folder structures. Teams find the right dataset in seconds, tier cold derivatives by policy, purge with an audit trail, and curate seismic and well data for AI.
Why it matters.
Exploration, processing, and decisions move on schedule instead of through tickets. Premium HPC capacity comes back from derivative and failed-run waste, so the next expansion is smaller or later. Lease and partnership cleanup runs in minutes with proof ready for regulators. Curated seismic and reservoir datasets reach AI and analytics pipelines in days, not weeks.
Why Diskover.
One catalog from HPC to tape.
Index every file across HPC scratch, NAS, object, cloud, and tape into one searchable view, by fields such as survey, well, format, and age, so one search covers raw seismic, derivatives, simulation runs, logs, and archive, with data staying in place.
Defensible deletion.
Tag every file tied to a lease, block, or partnership, run the purge as a policy with a preview, and keep an audit trail of what was removed, when, and by whom, so proof is ready inside the statutory window.
Energy fluency in the metadata.
Diskover recognizes the file types and project structures that Petrel, Eclipse, Kingdom, and GOCAD leave behind, so SEG-Y and .zgy derivatives, .egrid simulation backups, LAS well logs, and transient .tmp files are identified by metadata such as extension, path, and age.
Divestiture and M&A readiness.
Locate, validate, tag, and package the datasets attached to an asset or basin under deal deadlines, with an inventory the buyer and the auditor can both read. One energy customer located its divestiture data in under an hour, not weeks.
HPC-aware tiering.
When a run completes or fails, policy moves cold derivatives, failed-run outputs, and old iterations off premium HPC storage to NAS, object, or archive and keeps the catalog entry, so scratch capacity comes back without scripts, tickets, or someone remembering.
Ask in plain language.
Ask the catalog “which simulation outputs older than two years are still on HPC scratch” and get matching files back with a recommended action to approve, such as tier, purge, or package. AI-assisted, human-approved.
How it works.
1. Connect
Storage or IT team
Point Diskover at HPC file systems, NAS, object, cloud, and tape libraries. Indexing runs in place, so seismic volumes and simulation outputs stay where compute expects them.
Example: a seismic project share is cataloged where it sits.
2. Catalog
Automation
Every file becomes a searchable record with rich metadata, such as name, path, and owner, enriched with project and well tokens from the path and classification tags.
Example: a SEG-Y volume now shows its survey, well, owner, and age.
3. Curate
Any authorized team
Tag by fields such as survey, well, lease, and status. Build saved searches for what teams ask weekly, such as failed runs still on scratch, derivatives past retention, or files tied to a dissolved partnership.
Example: a geoscientist or data manager saves “failed runs” as a search.
4. Activate
By policy
Run tiering, purge, and packaging by policy with a full audit trail, and deliver curated seismic, log, and simulation metadata to analytics and AI pipelines through the API.
Result: at one energy company, 9 PB was inventoried ahead of a $60B merger.
Key outcomes.
Faster time to first oil.
Geoscientists and reservoir engineers find the right survey, run, or log in one search instead of tickets and email, so exploration, processing, and decisions move on schedule.
HPC that stays clean.
Storage teams reclaim 30% or more of premium HPC tiers by moving derivatives and failed runs off scratch by policy, so the next capacity purchase is smaller or later.
Compliance and AI-ready.
Lease and partnership cleanup runs in minutes with proof of purge ready, and curated seismic and well datasets reach AI and analytics pipelines in days instead of weeks.
Questions people ask.
Why does oil and gas exploration create so much unstructured data?
Seismic surveys, reservoir simulations, and well programs produce new iterations and derivatives at every stage, and each one is saved as files across HPC, NAS, cloud, and tape. Without a shared catalog, the same survey can exist in many versions, and failed runs and temporary files fill premium HPC storage.
How does Diskover find seismic and well data without opening the files?
Diskover reads the metadata that exploration and production tools leave behind, such as file extension, path, and age, and the project and well names in folder structures. That is how it identifies SEG-Y and .zgy derivatives, .egrid simulation backups, and LAS well logs, without reading file contents.
How can energy teams prove that lease or partnership data was deleted?
Teams tag every file tied to a lease, block, or partnership, run the purge as a policy with a preview, and keep an audit trail of what was removed, when, and by whom. That record is ready for regulators inside the statutory window. This approach is called defensible deletion.
Can Diskover free up HPC scratch storage after a run?
Yes. When a run completes or fails, a policy can move cold derivatives, failed-run outputs, and old iterations off premium HPC storage to NAS, object, or archive, and the file keeps its catalog entry. Storage teams reclaim 30% or more of premium HPC tiers this way, without scripts or tickets.
How fast can Diskover index an energy data estate?
Diskover has indexed 1.4 billion files in two hours, about 200,000 files per second. Rescans run faster, about 500,000 to 600,000 files per second, because Diskover skips folders that have not changed. Indexing runs in place, so seismic volumes and simulation outputs stay where compute expects them.
How often does Diskover re-index HPC scratch and tape?
Diskover indexes storage by volume, and you decide the indexing schedule for each one, based on its size and on how often its files change. HPC scratch with active simulation runs is often re-indexed every 10 to 30 minutes, while tape and archive volumes with finished surveys are usually re-indexed once a week or once a month. Rescans are faster than the first index, about 500,000 to 600,000 files per second, because Diskover skips folders that have not changed. See the Diskover FAQ.
Related resources.
See it on your own data.
We’ll index a sample of your environment and show you
what’s recoverable against your current storage spend.