

SOLUTION BRIEF | FINANCIAL SERVICES
Every record accounted for. Every audit answered.
One enriched metadata catalog for compliance, storage cost, and AI-ready data across your whole file estate.
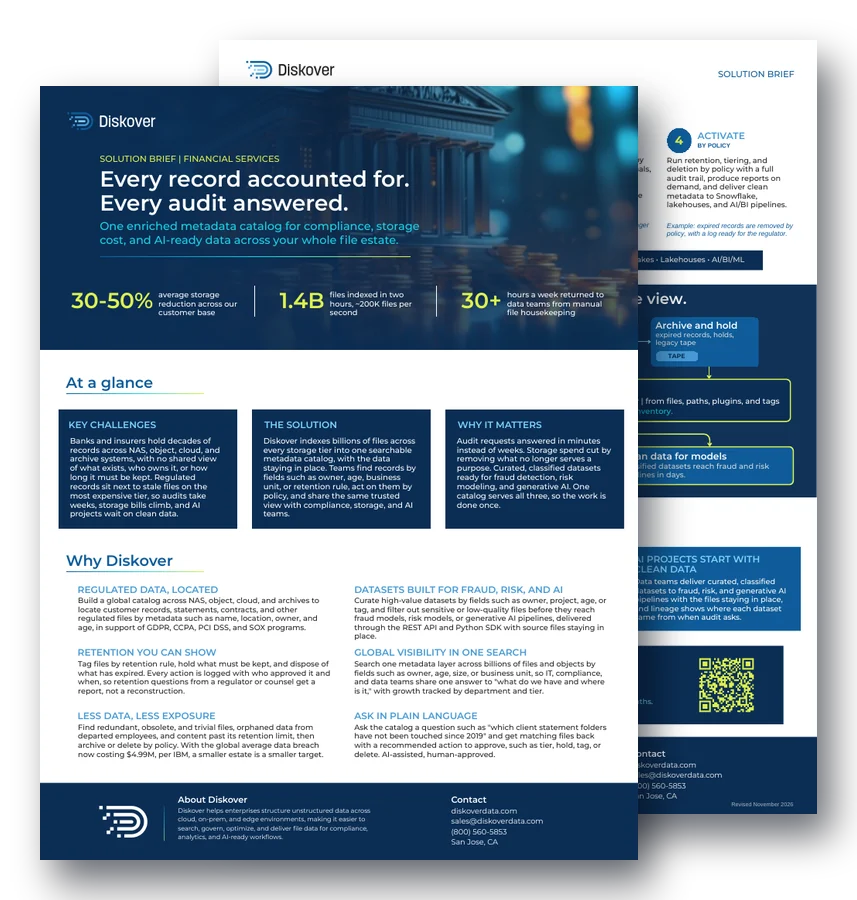
30-50%
average storage reduction across our customer base
1.4B
files indexed in two hours, about 200K files per second
30+
hours a week returned to data teams from manual file housekeeping
At a glance.
Key challenges.
Banks and insurers hold decades of records across NAS, object, cloud, and archive systems, with no shared view of what exists, who owns it, or how long it must be kept. Regulated records sit next to stale files on the most expensive tier, so audits take weeks, storage bills climb, and AI projects wait on clean data.
The solution.
Diskover indexes billions of files across every storage tier into one searchable metadata catalog, with the data staying in place. Teams find records by fields such as owner, age, business unit, or retention rule, act on them by policy, and share the same trusted view with compliance, storage, and AI teams.
Why it matters.
Audit requests are answered in minutes instead of weeks. Storage spend goes down by removing what no longer serves a purpose. Curated, classified datasets are ready for fraud detection, risk modeling, and generative AI. One catalog serves all three, so the work is done once.
Why Diskover.
Regulated data, located.
Build a global catalog across NAS, object, cloud, and archives to locate customer records, statements, contracts, and other regulated files by metadata such as name, location, owner, and age, in support of GDPR, CCPA, PCI DSS, and SOX programs.
Datasets built for fraud, risk, and AI.
Curate high-value datasets by fields such as owner, project, age, or tag, and filter out likely sensitive or low-quality files before they reach fraud models, risk models, or generative AI pipelines, delivered through the REST API and Python SDK with source files staying in place.
Retention you can show.
Tag files by retention rule, hold what must be kept, and dispose of what has expired. Every action is logged with who approved it and when, so retention questions from a regulator or counsel get a report, not a reconstruction.
Global visibility in one search.
Search one metadata catalog across billions of files and objects by fields such as owner, age, size, or business unit, so IT, compliance, and data teams share one answer to “what do we have and where is it,” with growth tracked by department and tier.
Less data, less exposure.
Find redundant, obsolete, and trivial files, orphaned data from departed employees, and content past its retention limit, then archive or delete by policy. With the global average data breach now costing $4.99M, per IBM, a smaller estate is a smaller target.
Ask in plain language.
Ask the catalog a question such as “which client statement folders have not been touched since 2019” and get matching files back with a recommended action to approve, such as tier, hold, tag, or delete. AI-assisted, human-approved.
How it works.
1. Connect
STORAGE OR IT TEAM
Point Diskover at NAS, SAN, object, cloud, tape, and archive storage. Indexing runs in place, so records stay where they are and where regulators expect them.
Example: a statements archive is cataloged where it sits.
2. Catalog
AUTOMATION
Every file becomes a searchable record with rich metadata, such as name, path, owner, and tags, enriched by plugins with business context such as department, retention class, or project.
Example: a client statement now shows its owner, age, and retention class.
3. Curate
ANY AUTHORIZED TEAM
Tag, classify, and group files by retention rule, sensitivity signals, or business unit. Build the datasets fraud, risk, and AI teams asked for, and leave the rest untouched.
Example: an auditor or records manager saves “files untouched since 2019”.
4. Activate
BY POLICY
Run retention, tiering, and deletion by policy with a full audit trail, produce reports on demand, and deliver clean metadata to Snowflake, lakehouses, and AI and BI pipelines.
Example: expired records are removed by policy, with a log ready for the regulator.
Key outcomes.
Weeks of discovery become minutes.
Compliance and legal teams find records across every system in one search instead of a manual multi-week data hunt, then export the list with owner, location, and retention status.
Storage spend goes down and stays down.
Storage teams surface cold, duplicate, and expired data and act on it by policy, so capacity comes back and the next storage purchase is smaller or later.
AI projects start with clean data.
Data teams deliver curated, classified datasets to fraud, risk, and generative AI pipelines with the files staying in place, and lineage shows where each dataset came from when audit asks.
Questions people ask.
How does Diskover help financial services firms answer an audit?
Diskover keeps one current metadata catalog of every file across NAS, object, cloud, and archive. Compliance teams search it by owner, location, age, or retention class and export the list, instead of asking every site for a manual inventory.
Does Diskover read the contents of customer records?
No. Diskover works from metadata, such as name, path, owner, size, and age, plus tags and fields that plugins add. File contents stay where they are and are not read.
How does Diskover support retention and defensible deletion?
Teams tag files by retention rule, protect what must be kept, and delete expired records by policy. Each action is logged with who approved it and when, which supports defensible deletion.
Which regulations does a metadata catalog support?
A catalog shows where regulated files live, who owns them, and how old they are. That inventory supports GDPR, CCPA, PCI DSS, and SOX programs, which all start with knowing what data you hold.
How do curated datasets reach fraud and risk models?
Data teams build datasets in the catalog by fields such as owner, project, age, or tag, leave out likely sensitive or low-quality files, and deliver the metadata through the REST API and Python SDK, with source files staying in place.
Related resources.
See it on your own data.
We’ll index a sample of your environment and show you
what’s recoverable against your current storage spend.