

SOLUTION BRIEF | MEDIA AND ENTERTAINMENT
From dailies to archive, every asset on the right tier.
One enriched metadata catalog for production, post, and the archive, across NAS, object, cloud, and tape.
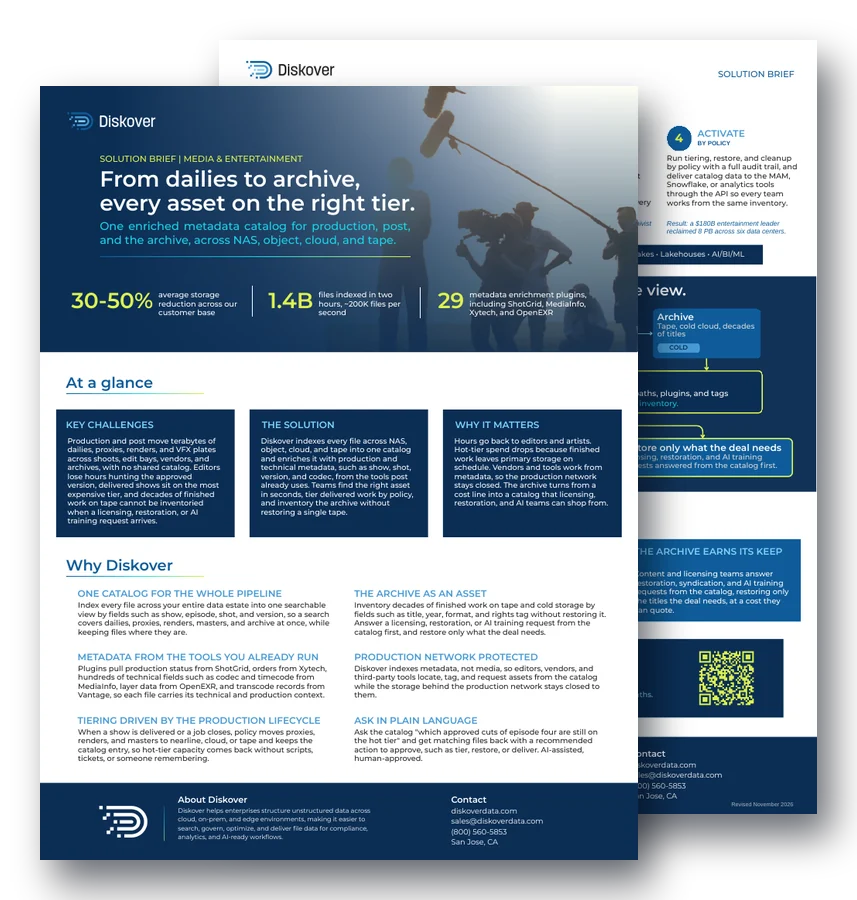
30-50%
average storage reduction across our customer base
1.4B
files indexed in two hours, about 200K files per second
29
metadata enrichment plugins, including ShotGrid, MediaInfo, Xytech, and OpenEXR
At a glance.
Key challenges.
Production and post move terabytes of dailies, proxies, renders, and VFX plates across shoots, edit bays, vendors, and archives, with no shared catalog. Editors lose hours hunting the approved version, delivered shows sit on the most expensive tier, and decades of finished work on tape cannot be inventoried when a licensing, restoration, or AI training request arrives.
The solution.
Diskover indexes every file across NAS, object, cloud, and tape into one catalog and enriches it with production and technical metadata, such as show, shot, version, and codec, from the tools post already uses. Teams find the right asset in seconds, tier delivered work by policy, and inventory the archive without restoring a single tape.
Why it matters.
Hours go back to editors and artists. Hot-tier spend drops because finished work leaves primary storage on schedule. Vendors and tools work from metadata, so the production network stays closed. The archive turns from a cost line into a catalog that licensing, restoration, and AI teams can shop from.
Why Diskover.
One catalog for the whole pipeline.
Index every file across your entire data estate into one searchable view by fields such as show, episode, shot, and version, so a search covers dailies, proxies, renders, masters, and archive at once, while keeping files where they are.
The archive as an asset.
Inventory decades of finished work on tape and cold storage by fields such as title, year, format, and rights tag without restoring it. Answer a licensing, restoration, or AI training request from the catalog first, and restore only what the deal needs.
Metadata from the tools you already run.
Plugins pull production status from ShotGrid, orders from Xytech Media, hundreds of technical fields such as codec and timecode from MediaInfo, image channel data from OpenEXR, and transcode records from Vantage, so each file carries its technical and production context. See the media plugins.
Production network protected.
Diskover indexes metadata, not media, so editors, vendors, and third-party tools locate, tag, and request assets from the catalog while the storage behind the production network stays closed to them.
Tiering driven by the production lifecycle.
When a show is delivered or a job closes, policy moves proxies, renders, and masters to nearline, cloud, or tape and keeps the catalog entry, so hot-tier capacity comes back without scripts, tickets, or someone remembering.
Ask in plain language.
Ask the catalog “which approved cuts of episode four are still on the hot tier” and get matching files back with a recommended action to approve, such as tier, restore, or deliver. AI-assisted, human-approved.
How it works.
1. Connect
STORAGE OR IT TEAM
Point Diskover at NAS, SAN, object, cloud, tape libraries, and archive systems. Indexing runs in place, so media stays on the production network and nothing is copied to build the catalog.
Example: the edit bay NAS is cataloged where it sits.
2. Catalog
AUTOMATION
Every file becomes a searchable record with rich metadata, such as name, path, and owner, enriched by plugins with hundreds of fields, such as codec, timecode, and production status.
Example: a render now lists its show, shot, codec, and status.
3. Curate
ANY AUTHORIZED TEAM
Tag by fields such as show, episode, version, and rights. Build saved searches for what editors ask for daily, such as approved cuts, orphaned renders, or masters past delivery still on the hot tier.
Example: an editor, producer, or archivist saves “masters past delivery” as a search.
4. Activate
BY POLICY
Run tiering, restore, and cleanup by policy with a full audit trail, and deliver catalog data to the MAM, Snowflake, or analytics tools through the API so every team works from the same inventory.
Result: a $180B entertainment leader reclaimed 8 PB across six data centers.
Key outcomes.
Hours back to creative teams.
Editors and artists find the approved version, proxy, or render in one search instead of tickets and emails, and spend the time editing, finishing, and shipping the work.
Hot-tier spend down and staying down.
Storage teams reclaim 30% or more of primary capacity by moving delivered work off the hot tier by policy, so the next expansion is smaller or later.
The archive earns its keep.
Content and licensing teams answer restoration, syndication, and AI training requests from the catalog, restoring only the titles the deal needs, at a cost they can quote.
Questions people ask.
How do editors find the approved version faster?
Diskover catalogs edit bays, vendors, and archive in one place, with production status from ShotGrid and technical fields from MediaInfo. One search returns the approved cut with its status and format.
Can Diskover inventory an archive on tape without restoring it?
Yes. Diskover catalogs finished work on tape and cold storage by fields such as title, year, format, and rights tag, so teams answer a request from the catalog and restore only what the deal needs.
Which media tools does Diskover connect to?
Plugins pull context from ShotGrid, Xytech Media, MediaInfo, OpenEXR, and Vantage, among the 29 metadata enrichment plugins Diskover offers.
Does Diskover copy or read media files?
No. Diskover indexes metadata in place, not media, so nothing is copied to build the catalog and the production network stays closed to vendors and tools.
How much storage can a studio reclaim?
A $180B entertainment leader reclaimed 8 PB across six data centers and saved $10M. Diskover customers see a 30% to 50% average storage reduction.
How often does Diskover re-index edit bays and the archive?
Diskover indexes storage by volume, and you decide the indexing schedule for each one, based on its size and on how often its files change. Edit bay and render volumes are often re-indexed every 10 to 30 minutes, while backup and archive volumes are usually re-indexed once a week or once a month. Rescans are faster than the first index, about 500,000 to 600,000 files per second, because Diskover skips folders that have not changed. See the Diskover FAQ.
Related resources.
See it on your own data.
We’ll index a sample of your environment and show you
what’s recoverable against your current storage spend.