

Category
- Cold data
- Dark data
- Data silos
- File metadata
- ROT data
- Semi-structured data
- Structured data
- Unstructured data
All categories
GlossaryUnstructured Data BasicsUnstructured data
Unstructured data
Unstructured data is information stored as files rather than as database records. Documents, images, video, audio, log files, design files, and instrument output all count. The name describes how the data is stored, not how orderly it is inside.
Key takeaways
- Unstructured data is held as files rather than database rows, such as documents, images, video, and audio.
- Most of an organization’s data is unstructured, and it grows faster than structured data.
- It becomes manageable through its metadata, indexed into one catalog across every storage system.
What are examples of unstructured data?
Unstructured data is any file whose contents do not sit in rows and columns. In media and entertainment, that means camera footage, render output, and project files. In life sciences, it means microscope images, sequencing output, and instrument logs. In semiconductor design, it means simulation results and verification logs. Across every industry, it also means the ordinary working files: documents, presentations, spreadsheets, email attachments, PDFs, design files, photographs, audio recordings, backups, and virtual machine images. A single production or research project can generate millions of them, which is why a data estate is usually counted in files rather than in records.
Who creates unstructured data?
People, and increasingly machines. People create documents, spreadsheets, presentations, and email attachments. Machines and applications create much of the rest: cameras and scanners, sensors and vehicles, lab instruments and sequencers, simulations and render farms, and the logs every system writes. Machine data tends to arrive continuously and in large volumes, but it often comes with useful records of its own, such as run logs or capture settings, which make it easier to describe if that metadata is kept.
What counts as unstructured data in practice?
Office documents and PDFs, images and video, audio, email archives, CAD and EDA design files, simulation and render output, log and telemetry files, backups, virtual machine images, and scientific formats such as BAM, FASTQ, DICOM, and MXF. If it arrives as a file on an NFS or SMB share or as an object in S3 or Azure Blob, it counts.
Are call recordings and other audio files unstructured data?
Yes. A call recording is a file with no fixed fields inside it, so it is unstructured data, like video, images, and documents. What is structured about it is its metadata, such as the file name, length, format, date, and the system it came from. Contact centers often store millions of these files, and describing them through metadata is what makes them searchable, reportable, and subject to retention rules.
What is an unstructured database?
The term is used for two different things. Sometimes it means a NoSQL or document database that stores records without a fixed schema, such as JSON documents. Sometimes it means a system that keeps files, such as documents, images, and video, together with a searchable description of them. In the second sense, the description is usually a metadata catalog: the files stay on storage, and the catalog holds the structured record that makes them findable.
How much of an organization’s data is unstructured?
Around 90% of the data organizations generate is unstructured, according to IDC research published in 2023. Some estates are almost entirely unstructured, because instruments and render farms produce files continuously. That pattern shows up in media and entertainment, life sciences and healthcare, semiconductor design, and energy.
Why does unstructured data grow faster than structured data?
Database growth is bounded by what applications write. File growth is bounded by what instruments, cameras, sensors, simulations, and people produce, and none of those has a natural stopping point. Higher resolution, larger models, and more sensors all multiply file size and file count at the same time.
How fast is unstructured data growing?
IDC predicted that organizations worldwide would generate more than 73,000 exabytes of unstructured data in 2023 alone, in a white paper sponsored by Box and published in August 2023. That volume rises every year with higher-resolution instruments, larger models, and more sensors. For any one organization, the useful measure is its own growth rate by project and team, which a metadata catalog reports from file sizes and dates.
Why is unstructured data harder to manage than database data?
A database describes itself. Every row sits in a named column with a defined type, so a rule can be written straight against the schema. Files carry no schema of their own, so a rule has to be written against attributes assembled from outside the file. That is a solvable problem, and it is why a file estate needs a catalog where a database needs only a query.
Who owns unstructured data inside an organization?
Ownership is usually recorded as the account that created the file, which drifts as people change roles and leave. That is why departed-employee data accumulates. Useful ownership has to be derived from the path, the project, the share, or an enrichment rule, rather than read from the file system. Until that is done, every question about who should decide on a file ends in a guess.
How do you manage unstructured data?
The same way as any other asset: know what you have, then decide what happens to it. The first step ends data silos, so one view covers every storage system:
- Index it. Build one catalog of file metadata across every storage system.
- Describe it. Add owners and business attributes such as project, department, and sensitivity.
- Set rules. Decide where each group should sit, how long it is kept, and who may reach it.
- Apply the rules on a schedule, and keep a record of every action.
How does Diskover help?
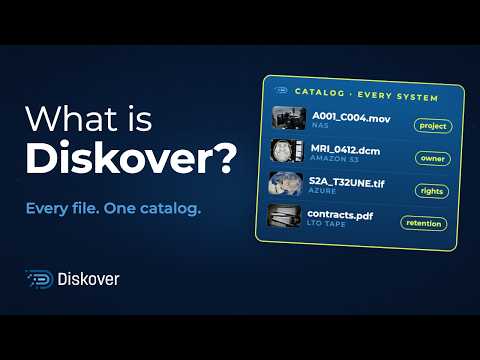
Diskover indexes the metadata of every file across your storage systems into one enriched catalog, so unstructured data can be searched, reported on, and acted on wherever it lives.
Sources
- IDC white paper sponsored by Box, Untapped Value: What Every Executive Needs to Know About Unstructured Data, August 2023: 90% of the data organizations generated in 2022 was unstructured.
- IDC white paper sponsored by Box, August 2023: organizations worldwide were predicted to generate more than 73,000 exabytes of unstructured data in 2023.
← Back to Unstructured Data Basics
Last updated: November 13, 2026.
See it on your own data.
We’ll index a sample of your environment and show you
what’s recoverable against your current storage spend.